
Hi, fellow future and current Data Leaders; Ben here 👋
Over the past few months I’ve been writing a series focused on going back to the basics. I’ve covered most of the various steps in an ETL/ELT as well as did some deeper dives into SQL.
Below are the links to the fuller series, but in this article, we’ll be focused on columar storage.
Back To The Basics
Data Pipelines
SQL Basics
With that out of the way, let’s jump into it!
Intro
Data engineers often discuss columnar storage, especially when discussing data warehouses or file formats like Parquet.
But why does it matter?
Why is columnar storage such a big deal for analytics? What makes it so well-suited for analytical use cases compared to other formats?
Maybe you already have a rough idea.
This article will help further explain columnar storage, why it’s used, and how it compares to row-based storage. It will also look at the most common formats and real-world use cases.
Let’s dive in.
What Is Columnar Storage?
To understand columnar storage, it helps to start with how it compares to row-based storage. Most databases don’t really make this distinction obvious; you just run SQL queries and get results. However, in the background, how the data is stored matters.
Let’s break down the difference between row-based and column-based storage.
Row-Based Storage
In row-based storage, data is stored one row at a time.
Imagine a table of customer orders with the following columns: order_id, product, order_date, and amount.
When an end-user places an order, the database inserts all of that data as a single row:

Row-based storage is optimized for transactional systems when you need to quickly read or write a full record. For example, when inserting a new order or updating an existing one.
As that information comes in, it is far more beneficial to store it in a row. That way, it’s quick to insert and update.
Columnar Storage
In columnar storage, data is stored by column instead of row by row.
Using the same order example, a columnar format would store the data like this:
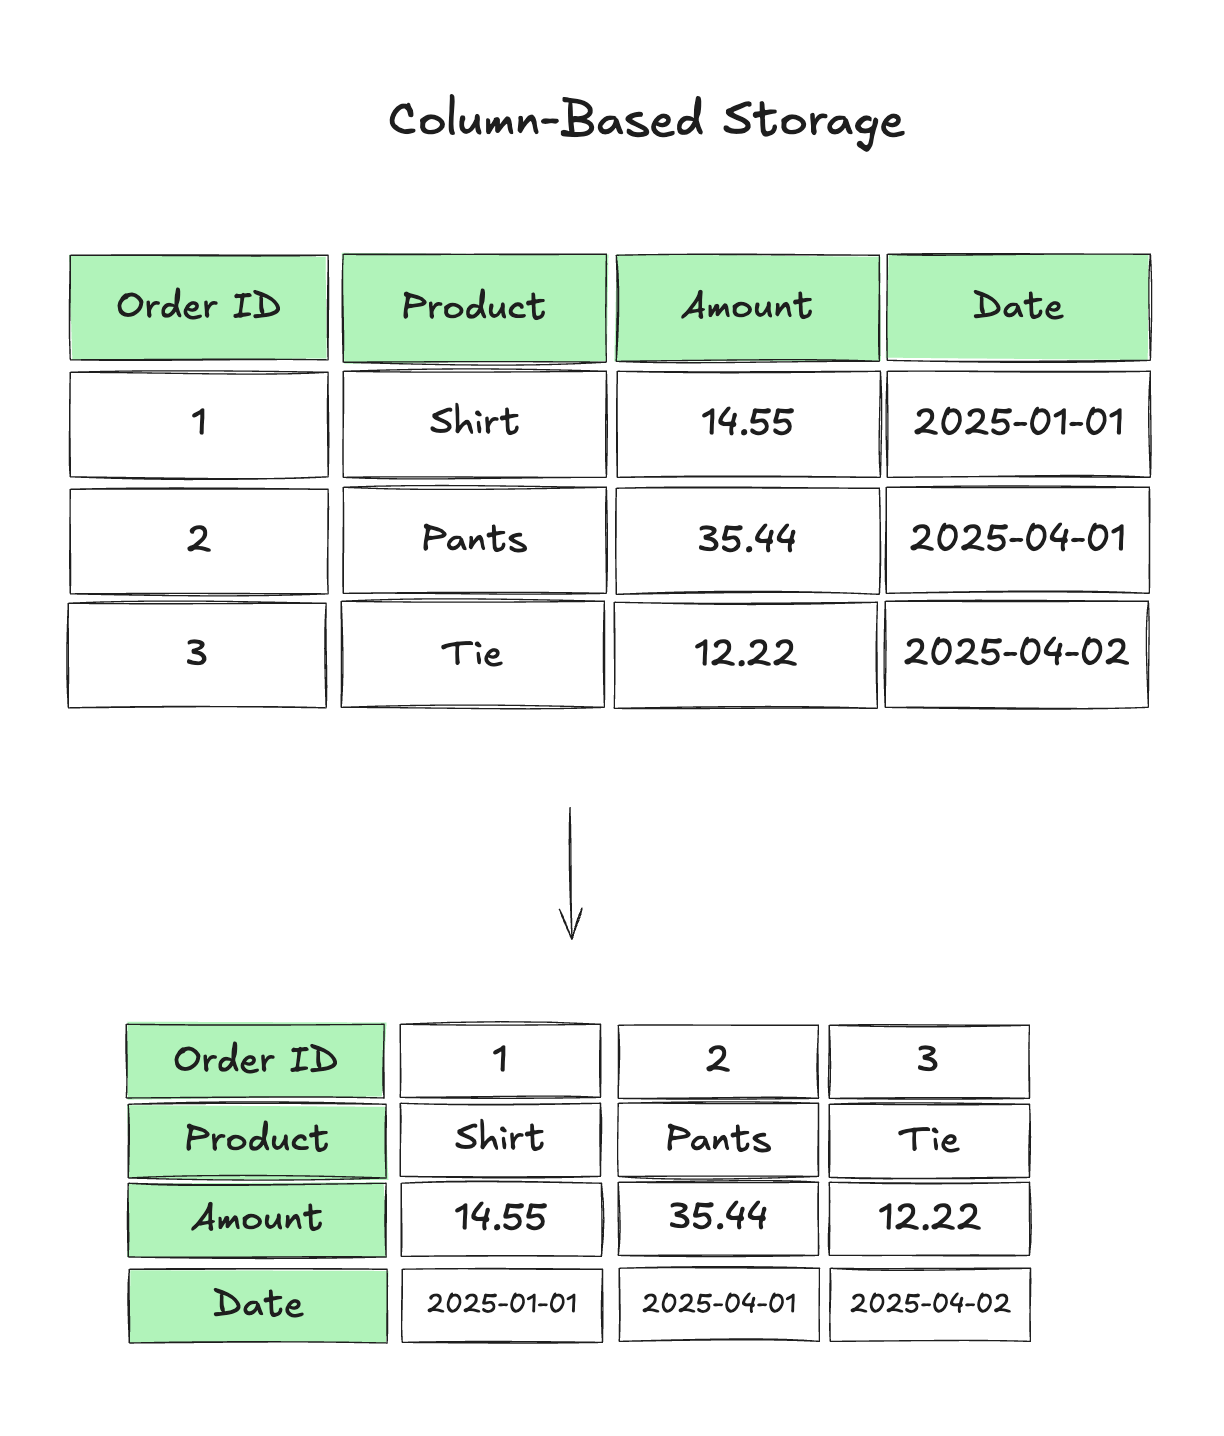
This works great for analytics. When you run queries that aggregate or filter by a few columns (think asking a question like “What’s the average order amount for the past month?”), columnar storage reduces the amount of data scanned and significantly improves performance.
That’s why analytical databases like BigQuery, Vertica, Snowflake, and Redshift are built with columnar storage under the hood.
I remember first really learning about the benefits of columnar storage and compression, for example, when I was digging into Redshift a decade ago. Of course, this begs the question...why?
